Platform information checked 2026-10-17. Supported backends include selected NVIDIA, AMD, Intel and Apple Silicon routes plus CPU-compatible options. Requirements depend on model and backend; the guide provides no universal speed or small-device promise. Models and caches can consume substantial disk. This qualifies local image generation. Supported paid API models do not become free because the interface is Apache-licensed.
Run a local web interface for image generation, refinement and processing.
Free local image generation · own hardware
Local inference has no required subscription, software purchase or paid model API. You supply compatible hardware, electricity, storage and initial downloads. SDXL weights have a separate Open RAIL++ license with use restrictions; software being open source does not make every model unrestricted. Optional cloud services, partner/API nodes and rented GPUs cost separately. This qualifies local image generation. Supported paid API models do not become free because the interface is Apache-licensed.
Run a local web interface for image generation, refinement and processing. A self-hosting option is recorded for this project. Review the official deployment instructions and maintenance requirements before running it yourself.
Release status
Official local installation route documented. This qualifies local image generation. Supported paid API models do not become free because the interface is Apache-licensed.
Install on your computer · Instructions checked 2026-10-17
Install the provider-supported Git and Python versions, then obtain SD.Next from its official repository in a normal writable user folder.
Choose the compute backend for your GPU/CPU before the first launch. Run webui.bat or webui.ps1 on Windows, or webui.sh on Linux/macOS, following that backend’s instructions.
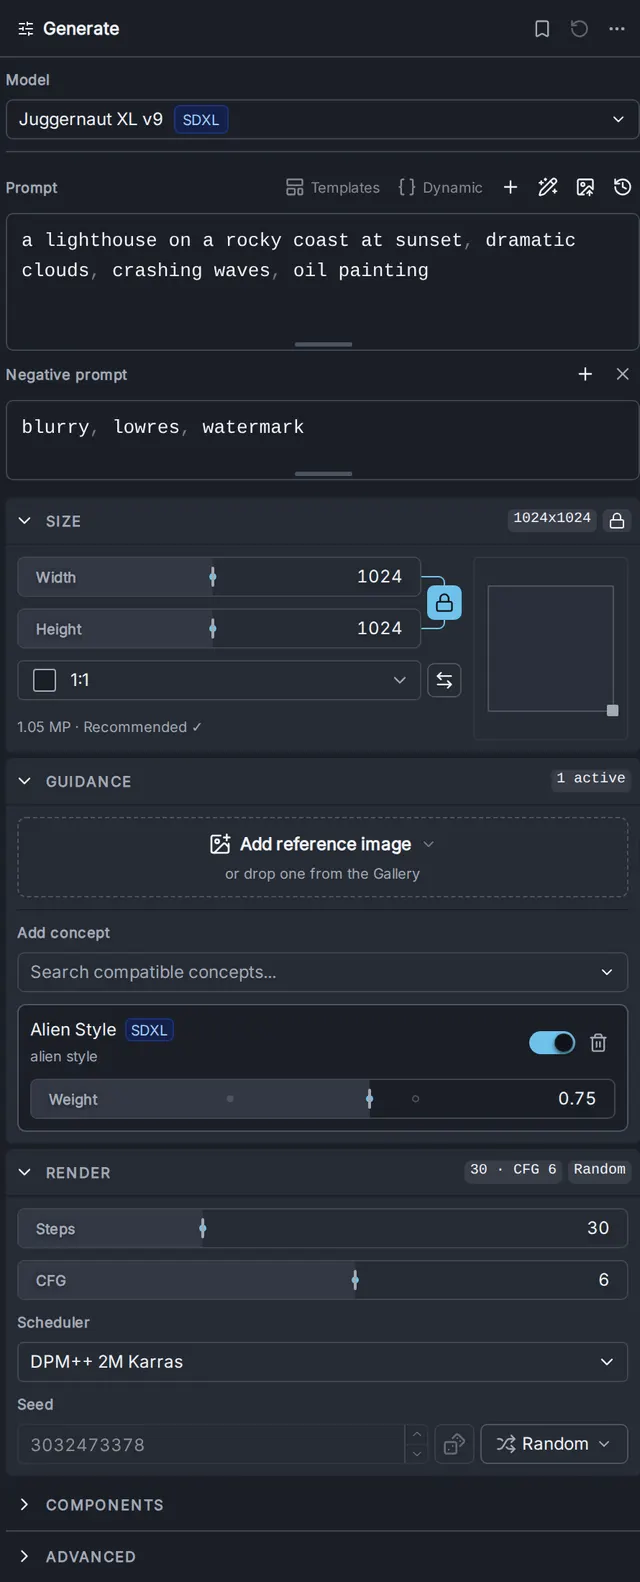
After dependencies finish, open the Local URL shown in the console. Use a compatible local SDXL reference/downloaded model and wait for its download/load.
Generate a small test image from the Text tab and inspect it. Keep separately billed API models and integrations disabled for this local route.
Supported backends include selected NVIDIA, AMD, Intel and Apple Silicon routes plus CPU-compatible options. Requirements depend on model and backend; the guide provides no universal speed or small-device promise. Models and caches can consume substantial disk. This qualifies local image generation. Supported paid API models do not become free because the interface is Apache-licensed.
Build and run local node-based image generation workflows.
Local inference has no required subscription, software purchase or paid model API. You supply compatible hardware, electricity, storage and initial downloads. SDXL weights have a separate Open RAIL++ license with use restrictions; software being open source does not make every model unrestricted. Optional cloud services, partner/API nodes and rented GPUs cost separately. Use a local SDXL workflow, not an API-node template. The core and desktop wrapper have different open-source licenses; cloud hosting is a separate paid edition.
Generate images locally through a prompt-focused SDXL interface.
Local inference has no required subscription, software purchase or paid model API. You supply compatible hardware, electricity, storage and initial downloads. SDXL weights have a separate Open RAIL++ license with use restrictions; software being open source does not make every model unrestricted. Optional cloud services, partner/API nodes and rented GPUs cost separately. Limited long-term support with bug fixes only; the observed default-branch commit is September 2025. Do not describe it as an actively developed current-model platform. Model checkpoints retain separate terms.
Generate and edit images on a local canvas with downloaded diffusion models.
Local inference has no required subscription, software purchase or paid model API. You supply compatible hardware, electricity, storage and initial downloads. SDXL weights have a separate Open RAIL++ license with use restrictions; software being open source does not make every model unrestricted. Optional cloud services, partner/API nodes and rented GPUs cost separately. The Community software is distinct from hosted/commercial products. This selection covers local image generation, not proprietary paid model access.
Use local generative fill, inpainting and image generation inside Krita.
Local inference has no required subscription, software purchase or paid model API. You supply compatible hardware, electricity, storage and initial downloads. SDXL weights have a separate Open RAIL++ license with use restrictions; software being open source does not make every model unrestricted. Optional cloud services, partner/API nodes and rented GPUs cost separately. Krita alone is not counted as an AI generator: this choice requires the separate plugin and local backend. Optional Interstice cloud service is separately priced.