Serve language models through an inference engine designed for throughput and efficient resource use.
Free serving software · compute costs
The Apache-2.0 serving software is free. Models, GPU hardware, electricity, storage and cloud compute have separate terms and costs. Installing the runtime does not include a hosted inference allowance.
Serve language models through an inference engine designed for throughput and efficient resource use. A self-hosting option is recorded for this project. Review the official deployment instructions and maintenance requirements before running it yourself.
Local models are free to run on your own hardware. Cloud Free includes limited starter usage; Pro is USD 20/month and Max USD 100/month. Usage credits and model token rates apply, and paid allowances do not roll over.
Run language model inference across different hardware with a portable C and C++ engine.
The MIT-licensed inference runtime has no software license fee. Supply suitable hardware and check each model license. Rented GPU or server resources and unrelated hosted services can cost extra.
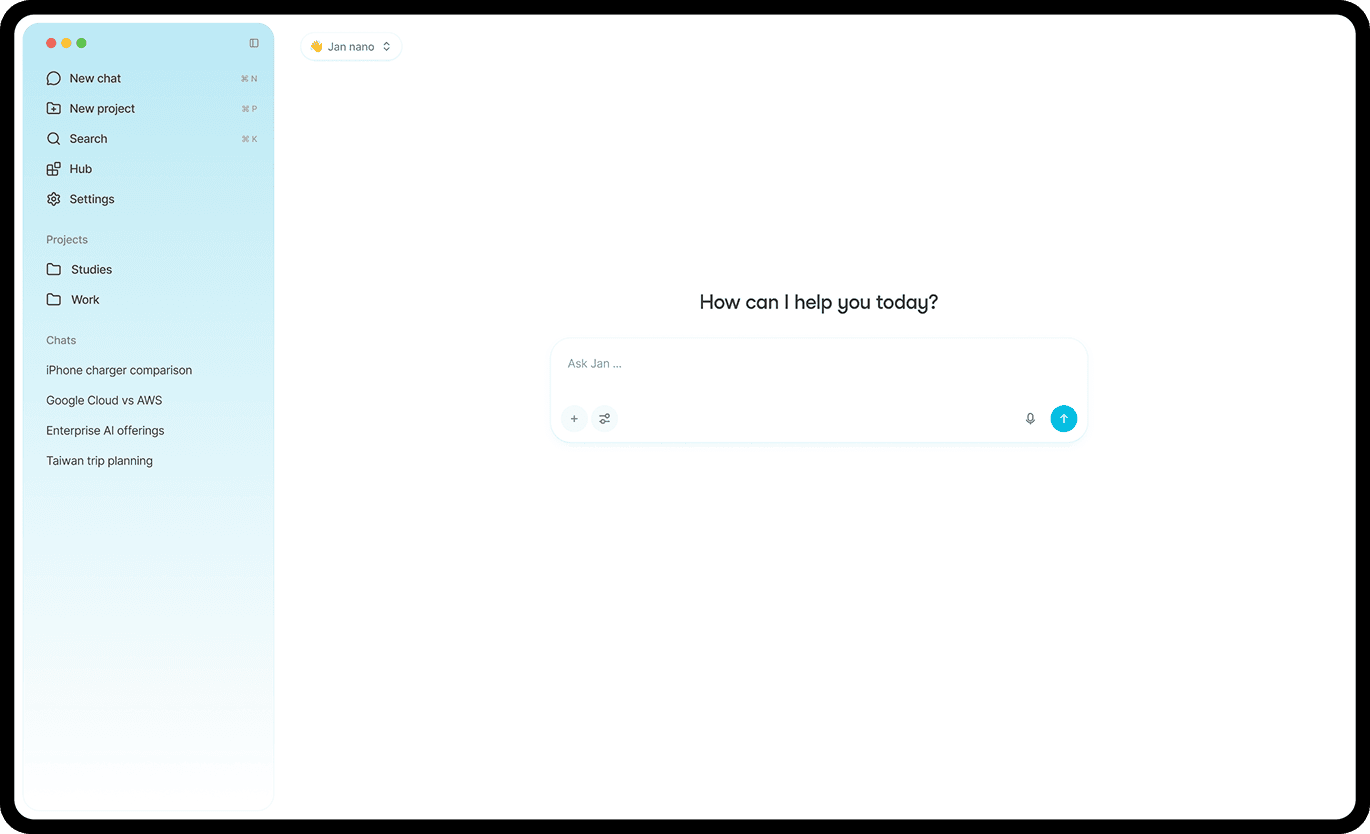
Chat with AI on your computer, including offline models.
Jan Desktop is free under Apache-2.0. Local inference has no per-message software fee; hardware, electricity and model licenses still apply. Connected cloud providers have their own API prices.